Blog
Research notes and updates on AI coding agents, verification, and shipping code you can trust.
Also on Medium Serkan OzalOct 19, 2026 · 49 min read
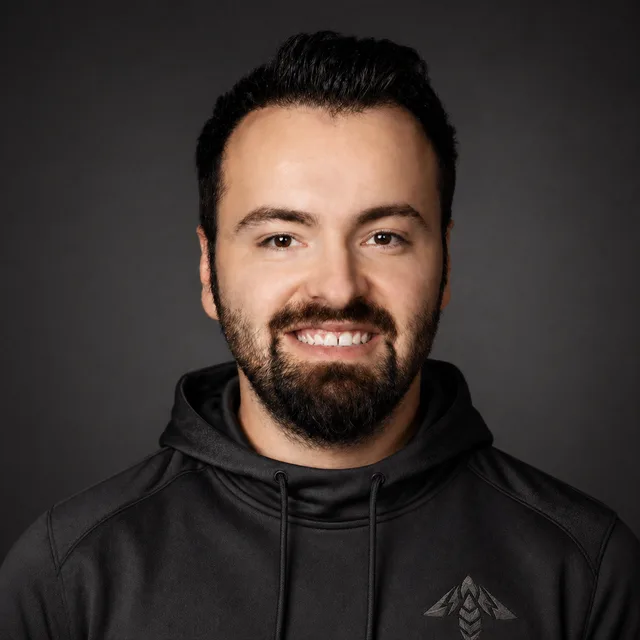
The Honest Raw LLM Code Review Benchmark: 21 Models, 7,980 Reviews, Every Number Open
We ran 21 raw LLMs at up to three effort levels on the 50 real pull requests of Martian's Code Review Bench, three times each, judged them with a calibrated three-model panel, and measured cost and speed for every configuration. We judged the 21 code review tools of Martian's public leaderboard with the same panel: the best raw models score as high as the best tools.
Read the post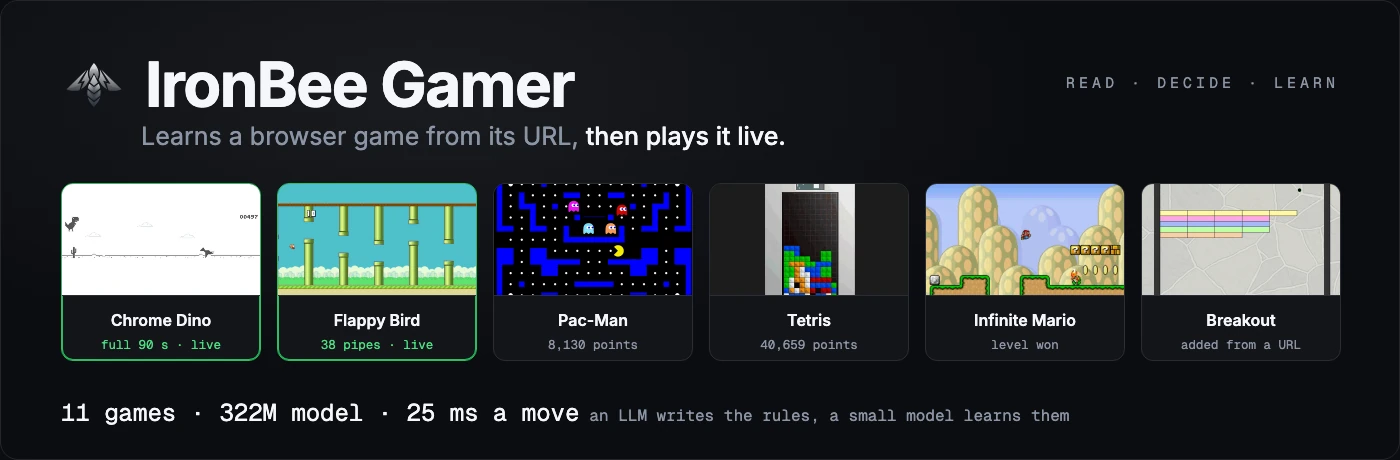 Serkan OzalOct 15, 2026 · 20 min read
How We Trained an AI Model to Play Browser Games Live
IronBee Gamer turns a browser game's URL into a trained AI model that plays it live. An LLM writes the rules, a 322M model is trained on them and makes a move in 22 to 45 ms, and here is what broke on the way.
Read the post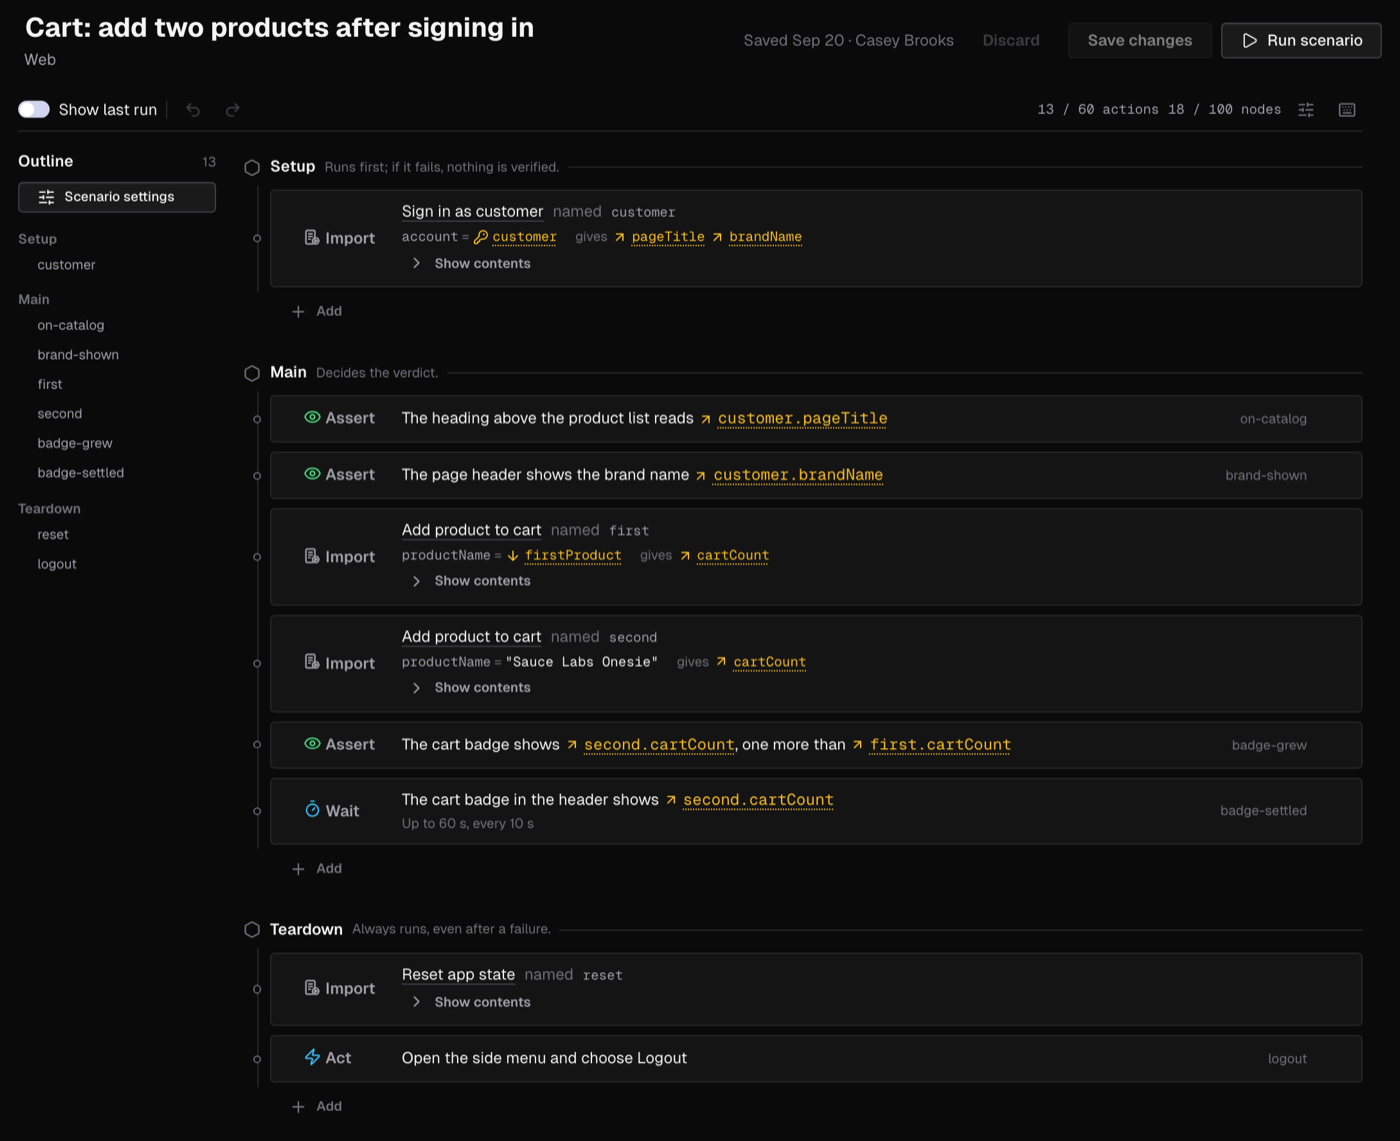 Ercan ErOct 13, 2026 · 11 min read
IronBee Scenarios: Write the Test in Sentences, Let the Harness Run It
IronBee Scenarios are plain-language end-to-end tests. You write the flow you click through before every release as sentences, and a harness hands an agent one action at a time and keeps the evidence of each.
Read the post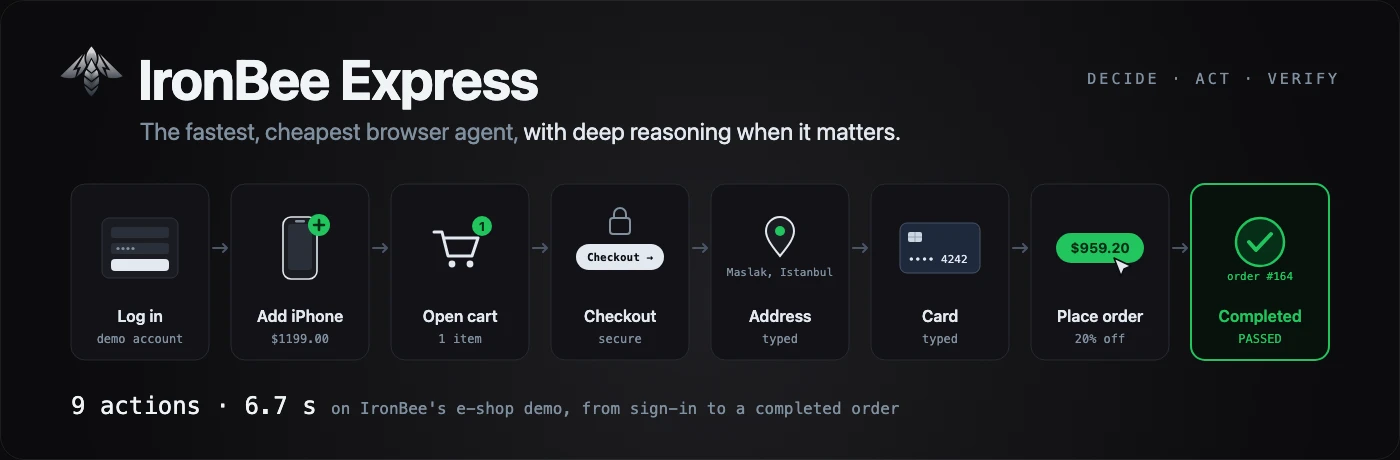 Serkan OzalOct 5, 2026 · 27 min read
How We Built the Fastest, Cheapest Browser Agent with Jev
IronBee Express runs a nine-action checkout in 6.7 seconds for $0.0005 in model cost. Here is what we ask Jev, what we show it, how it judges a run, and when we hand the wheel to an LLM.
Read the post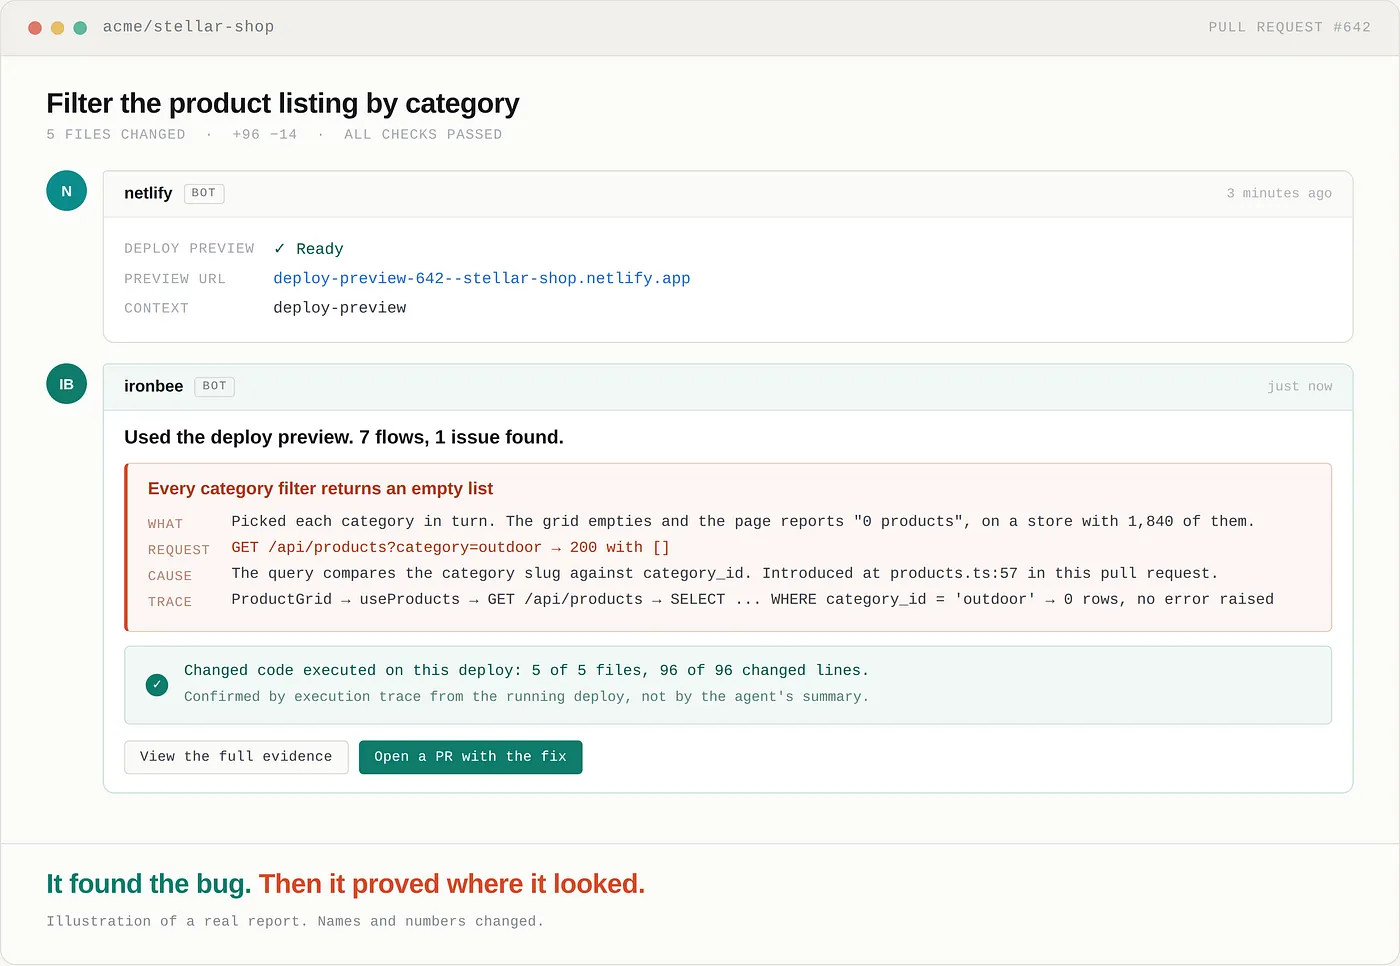 Serkan OzalSep 1, 2026 · 8 min read
Your AI QA Engineer Now Runs on Every Netlify Deploy
IronBee opens the deploy Netlify just built, uses your application on it, and checks that the code you changed actually ran. Automatic, on every pull request, before anything reaches production.
Read the post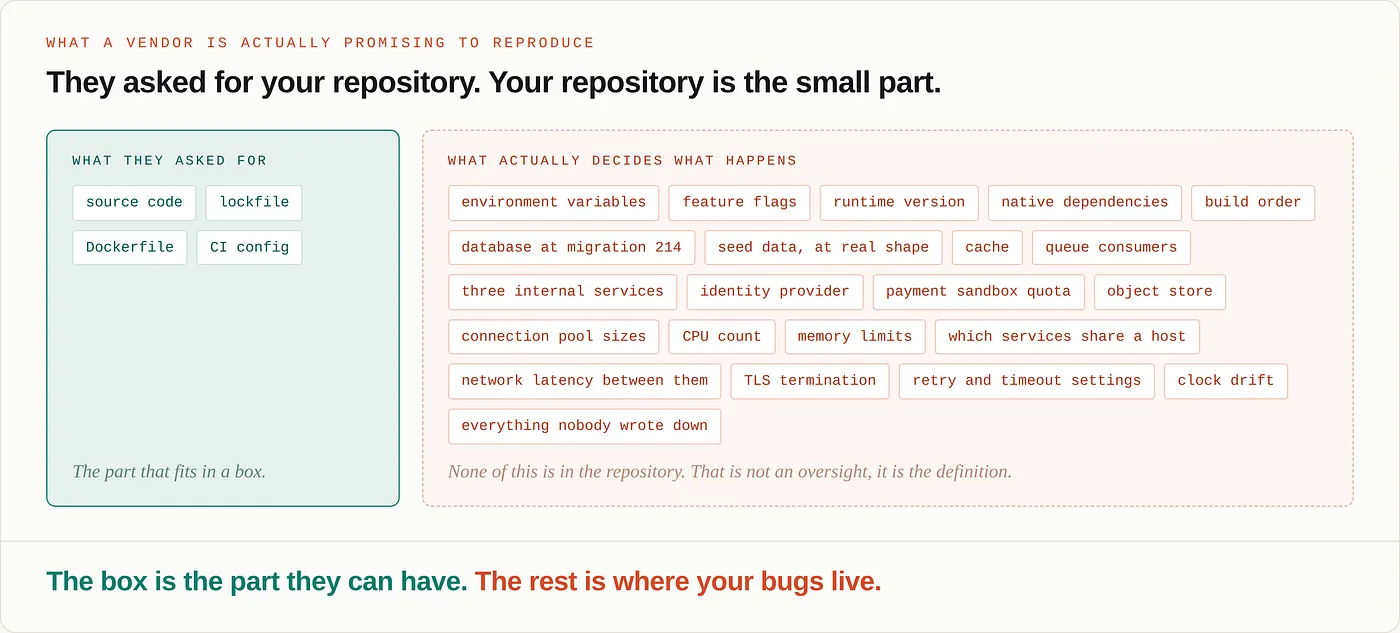 Serkan OzalAug 25, 2026 · 9 min read
Nobody Can Run Your App but You
Every testing tool that asks for your repository is promising to rebuild an environment it has never seen. It will get most of it right. The part it gets wrong is where your bugs live.
Read the post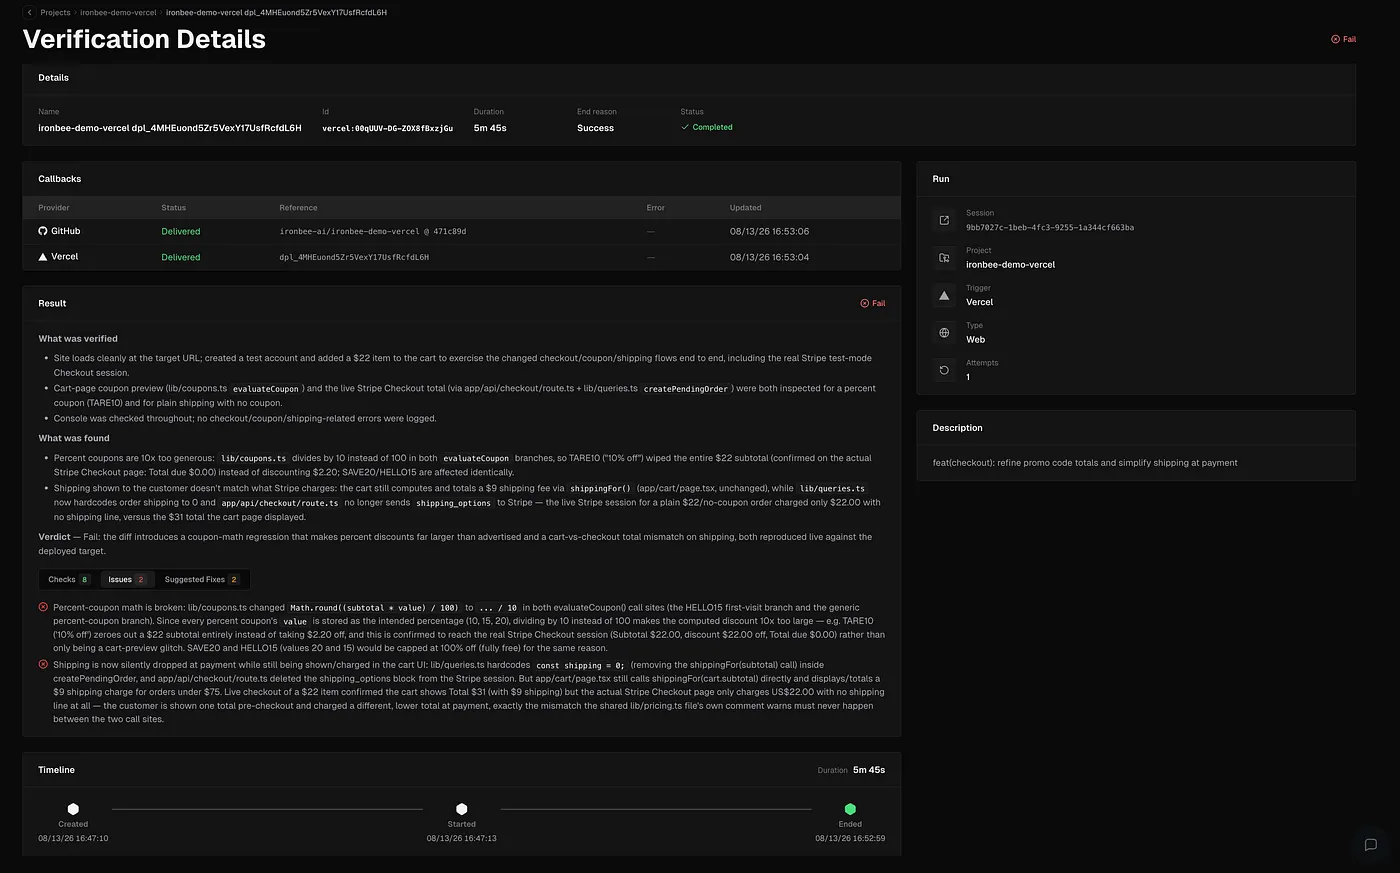 Serkan OzalAug 14, 2026 · 7 min read
Your AI QA Engineer Now Runs on Every Vercel Preview
IronBee opens the preview deployment nobody opens, uses your app the way a person would, and comes back on the pull request with the root cause. It runs inside CI too, with nothing deployed at all.
Read the post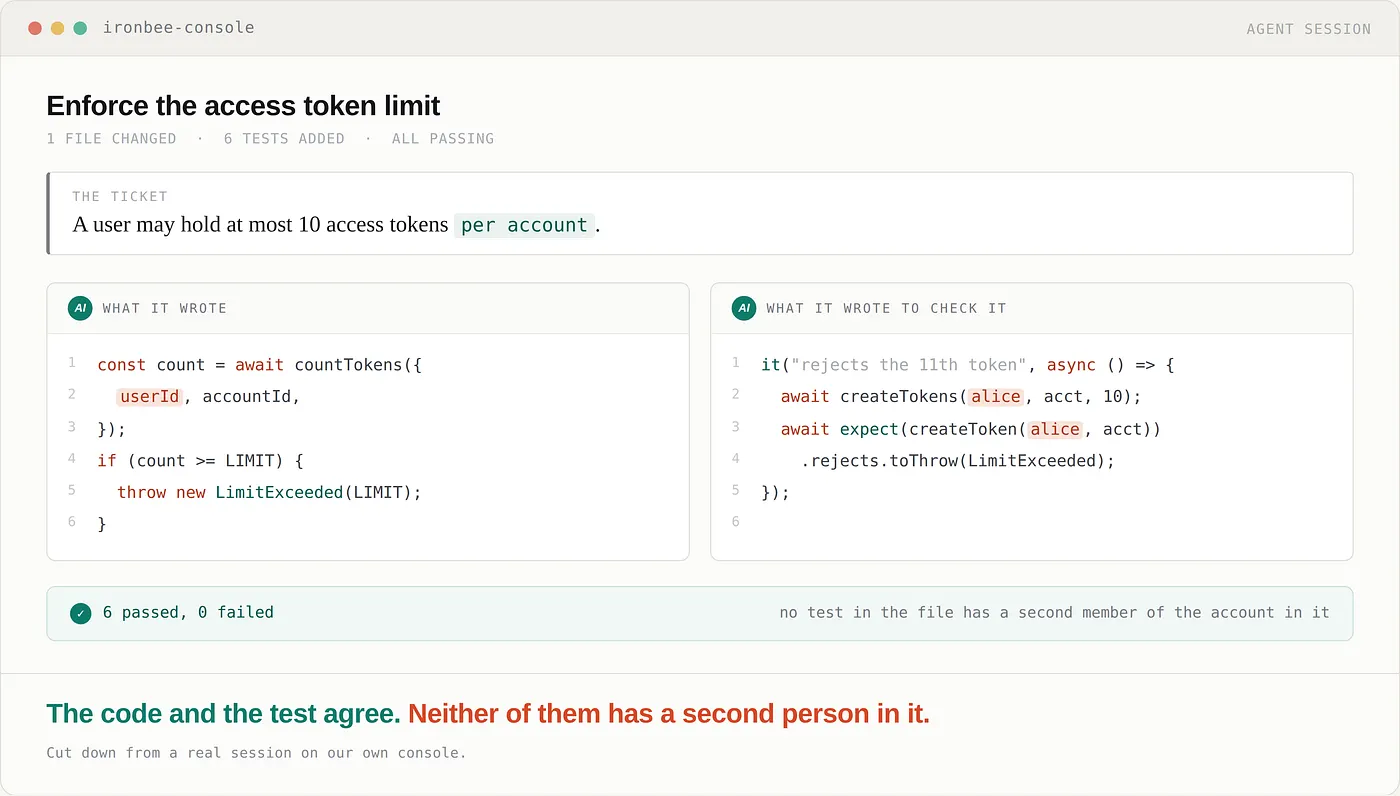 Serkan OzalAug 14, 2026 · 9 min read
Nobody Writes a Test for the Bug They Did Not Think Of
Ask a model to write tests and it grades its own homework, on the questions it chose. Ask it to use the software and it has to meet an answer it did not write.
Read the post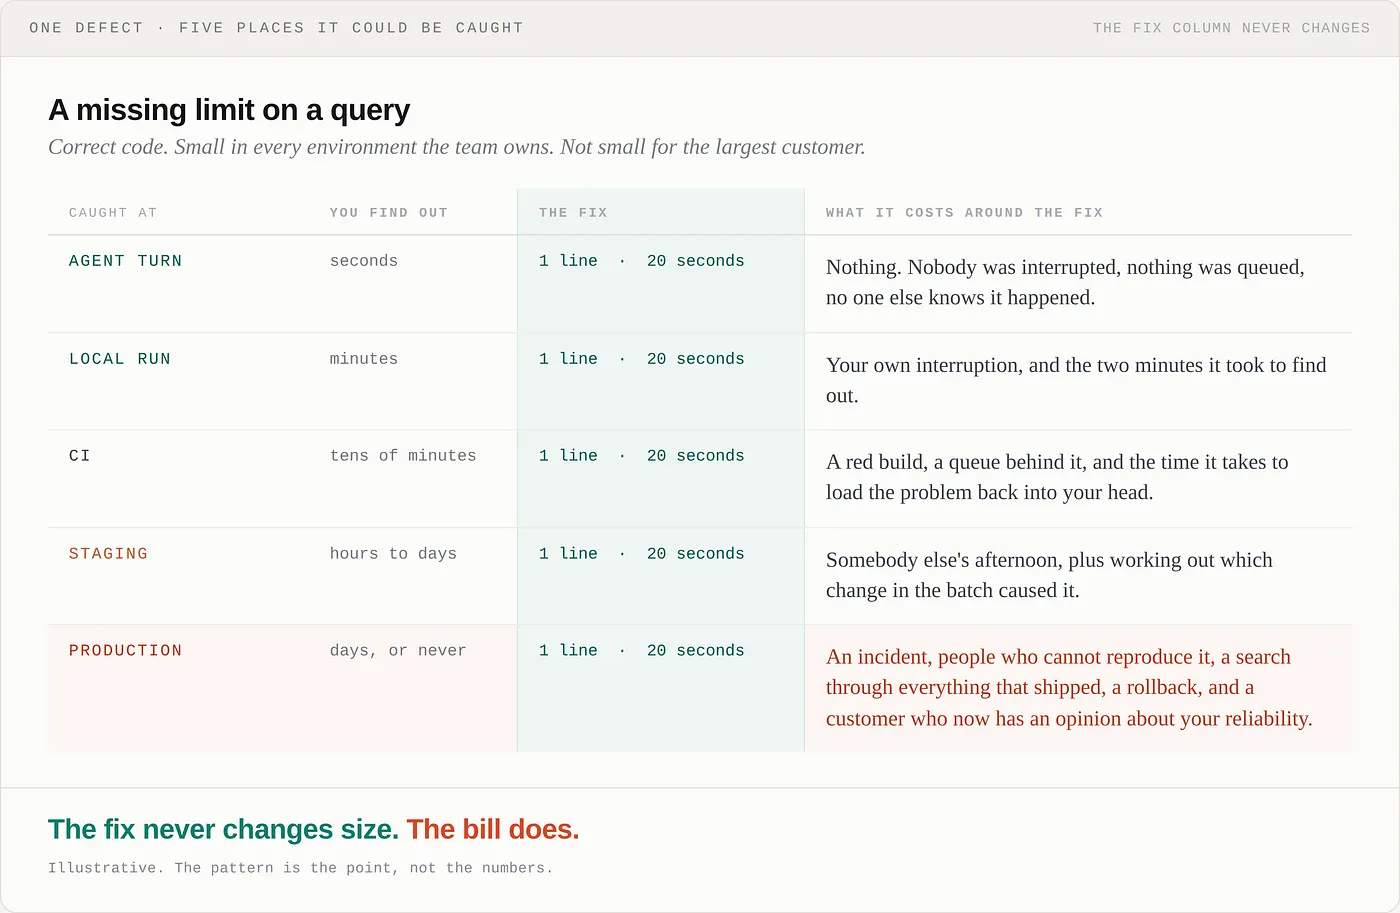 Serkan OzalAug 14, 2026 · 10 min read
The Price of a Bug Is Set by Where You Catch It
The same one line defect costs twenty seconds at the keystroke and a week in production. Adding another gate does not change that number. Moving the check inward does.
Read the post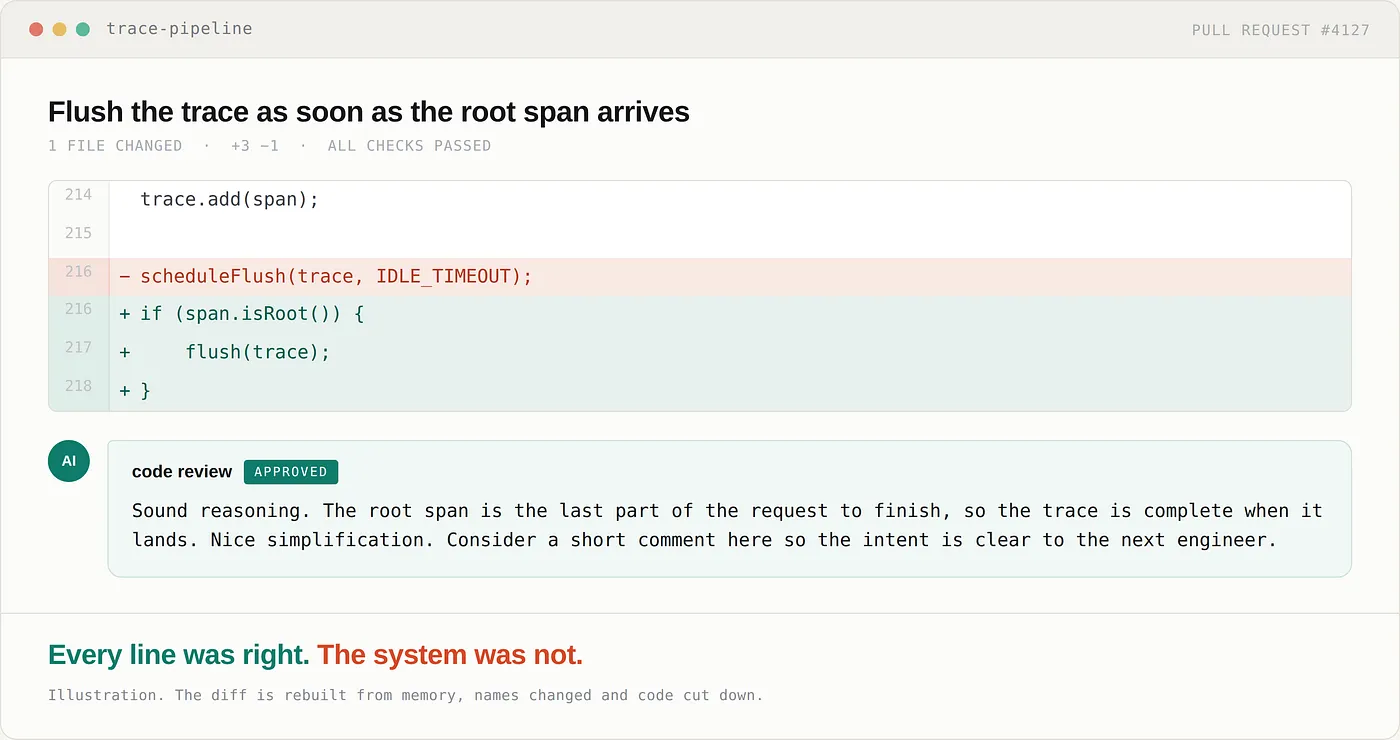 Serkan OzalAug 10, 2026 · 9 min read
Some bugs do not exist until you run the code
Static analysis and AI review can only judge how a change looks. The bugs that cost the most do not exist until the code runs.
Read the post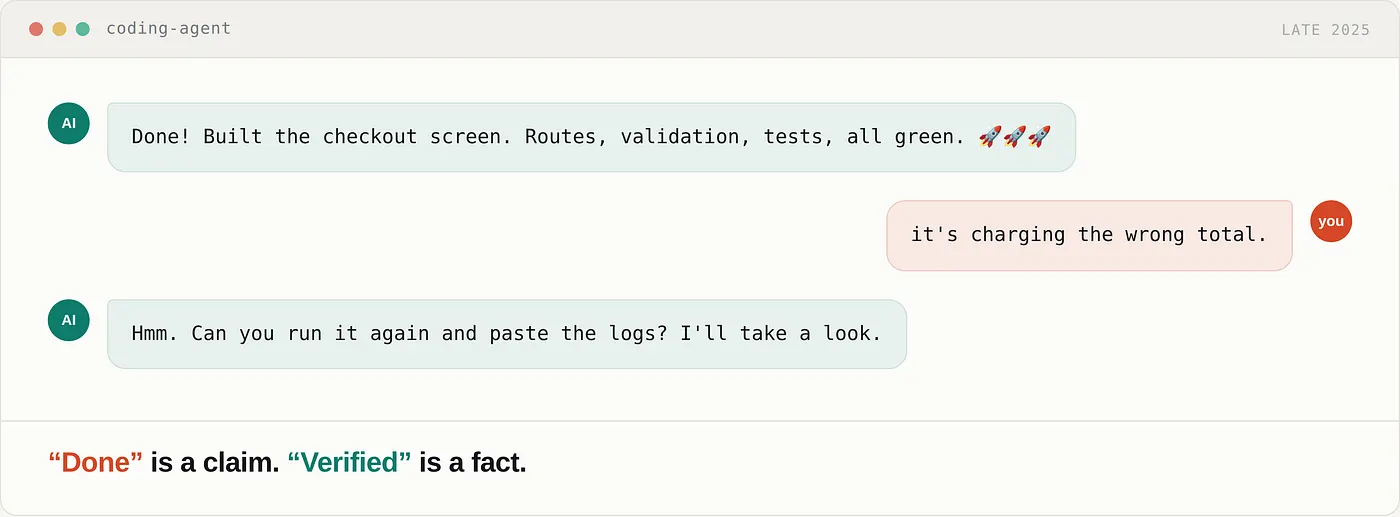 IronBeeAug 6, 2026 · 6 min read
I became the QA engineer for my own coding agent. Help!
Your coding agent writes in an hour what your team used to write in a sprint. The part that decides whether that code is any good did not speed up at all.
Read the post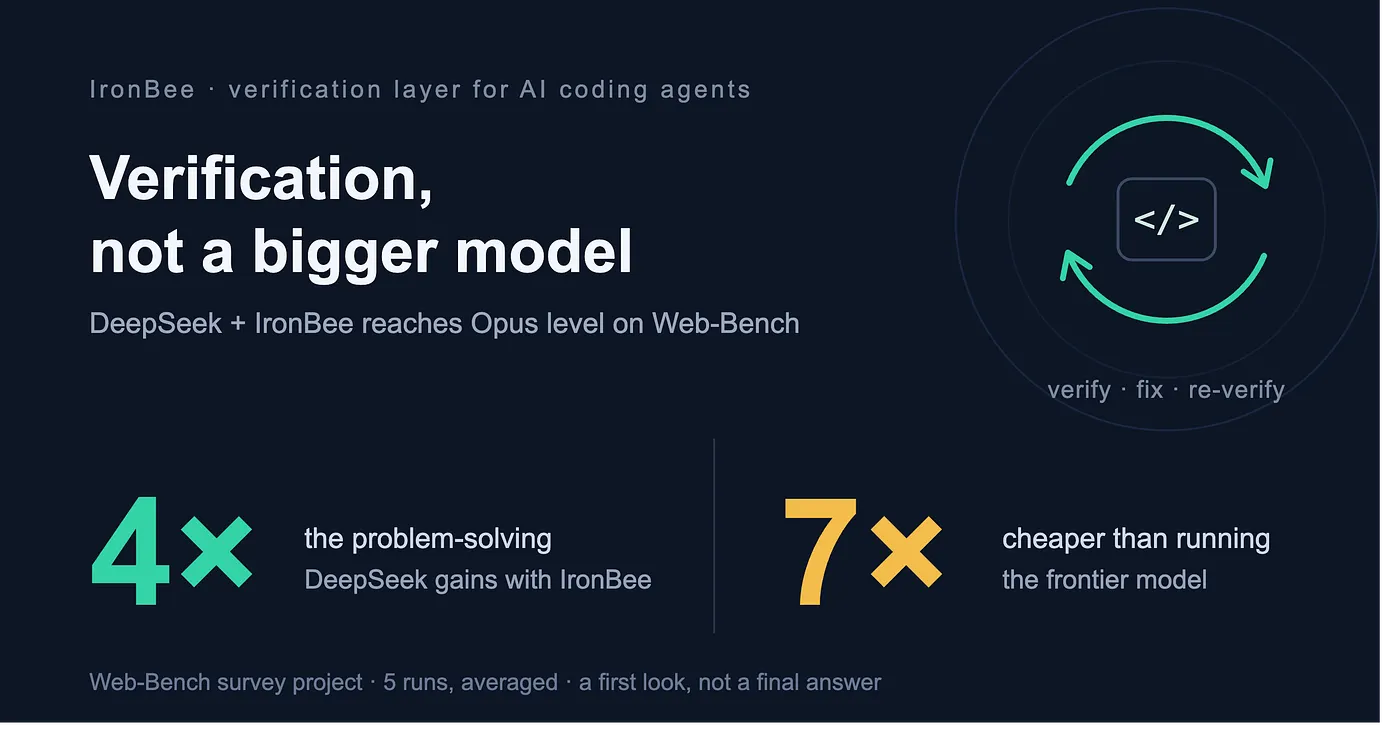 IronBeeAug 6, 2026 · 15 min read
What a Verification Loop Adds to a Coding Agent: A First Look
This is the opening post in an ongoing series. We start with one model pair on one project, and the analysis will continue across more models and more datasets. We are sharing early on purpose, and we will keep sharing as we go.
Read the post Serkan OzalAug 6, 2026 · 8 min read
Introducing IronBee: The Verification and Intelligence Layer for AI Coding Agents
AI coding agents are fast. They generate features, fix bugs, refactor code, often in minutes. But there’s a problem nobody talks about: they almost never verify their own work.
Read the post